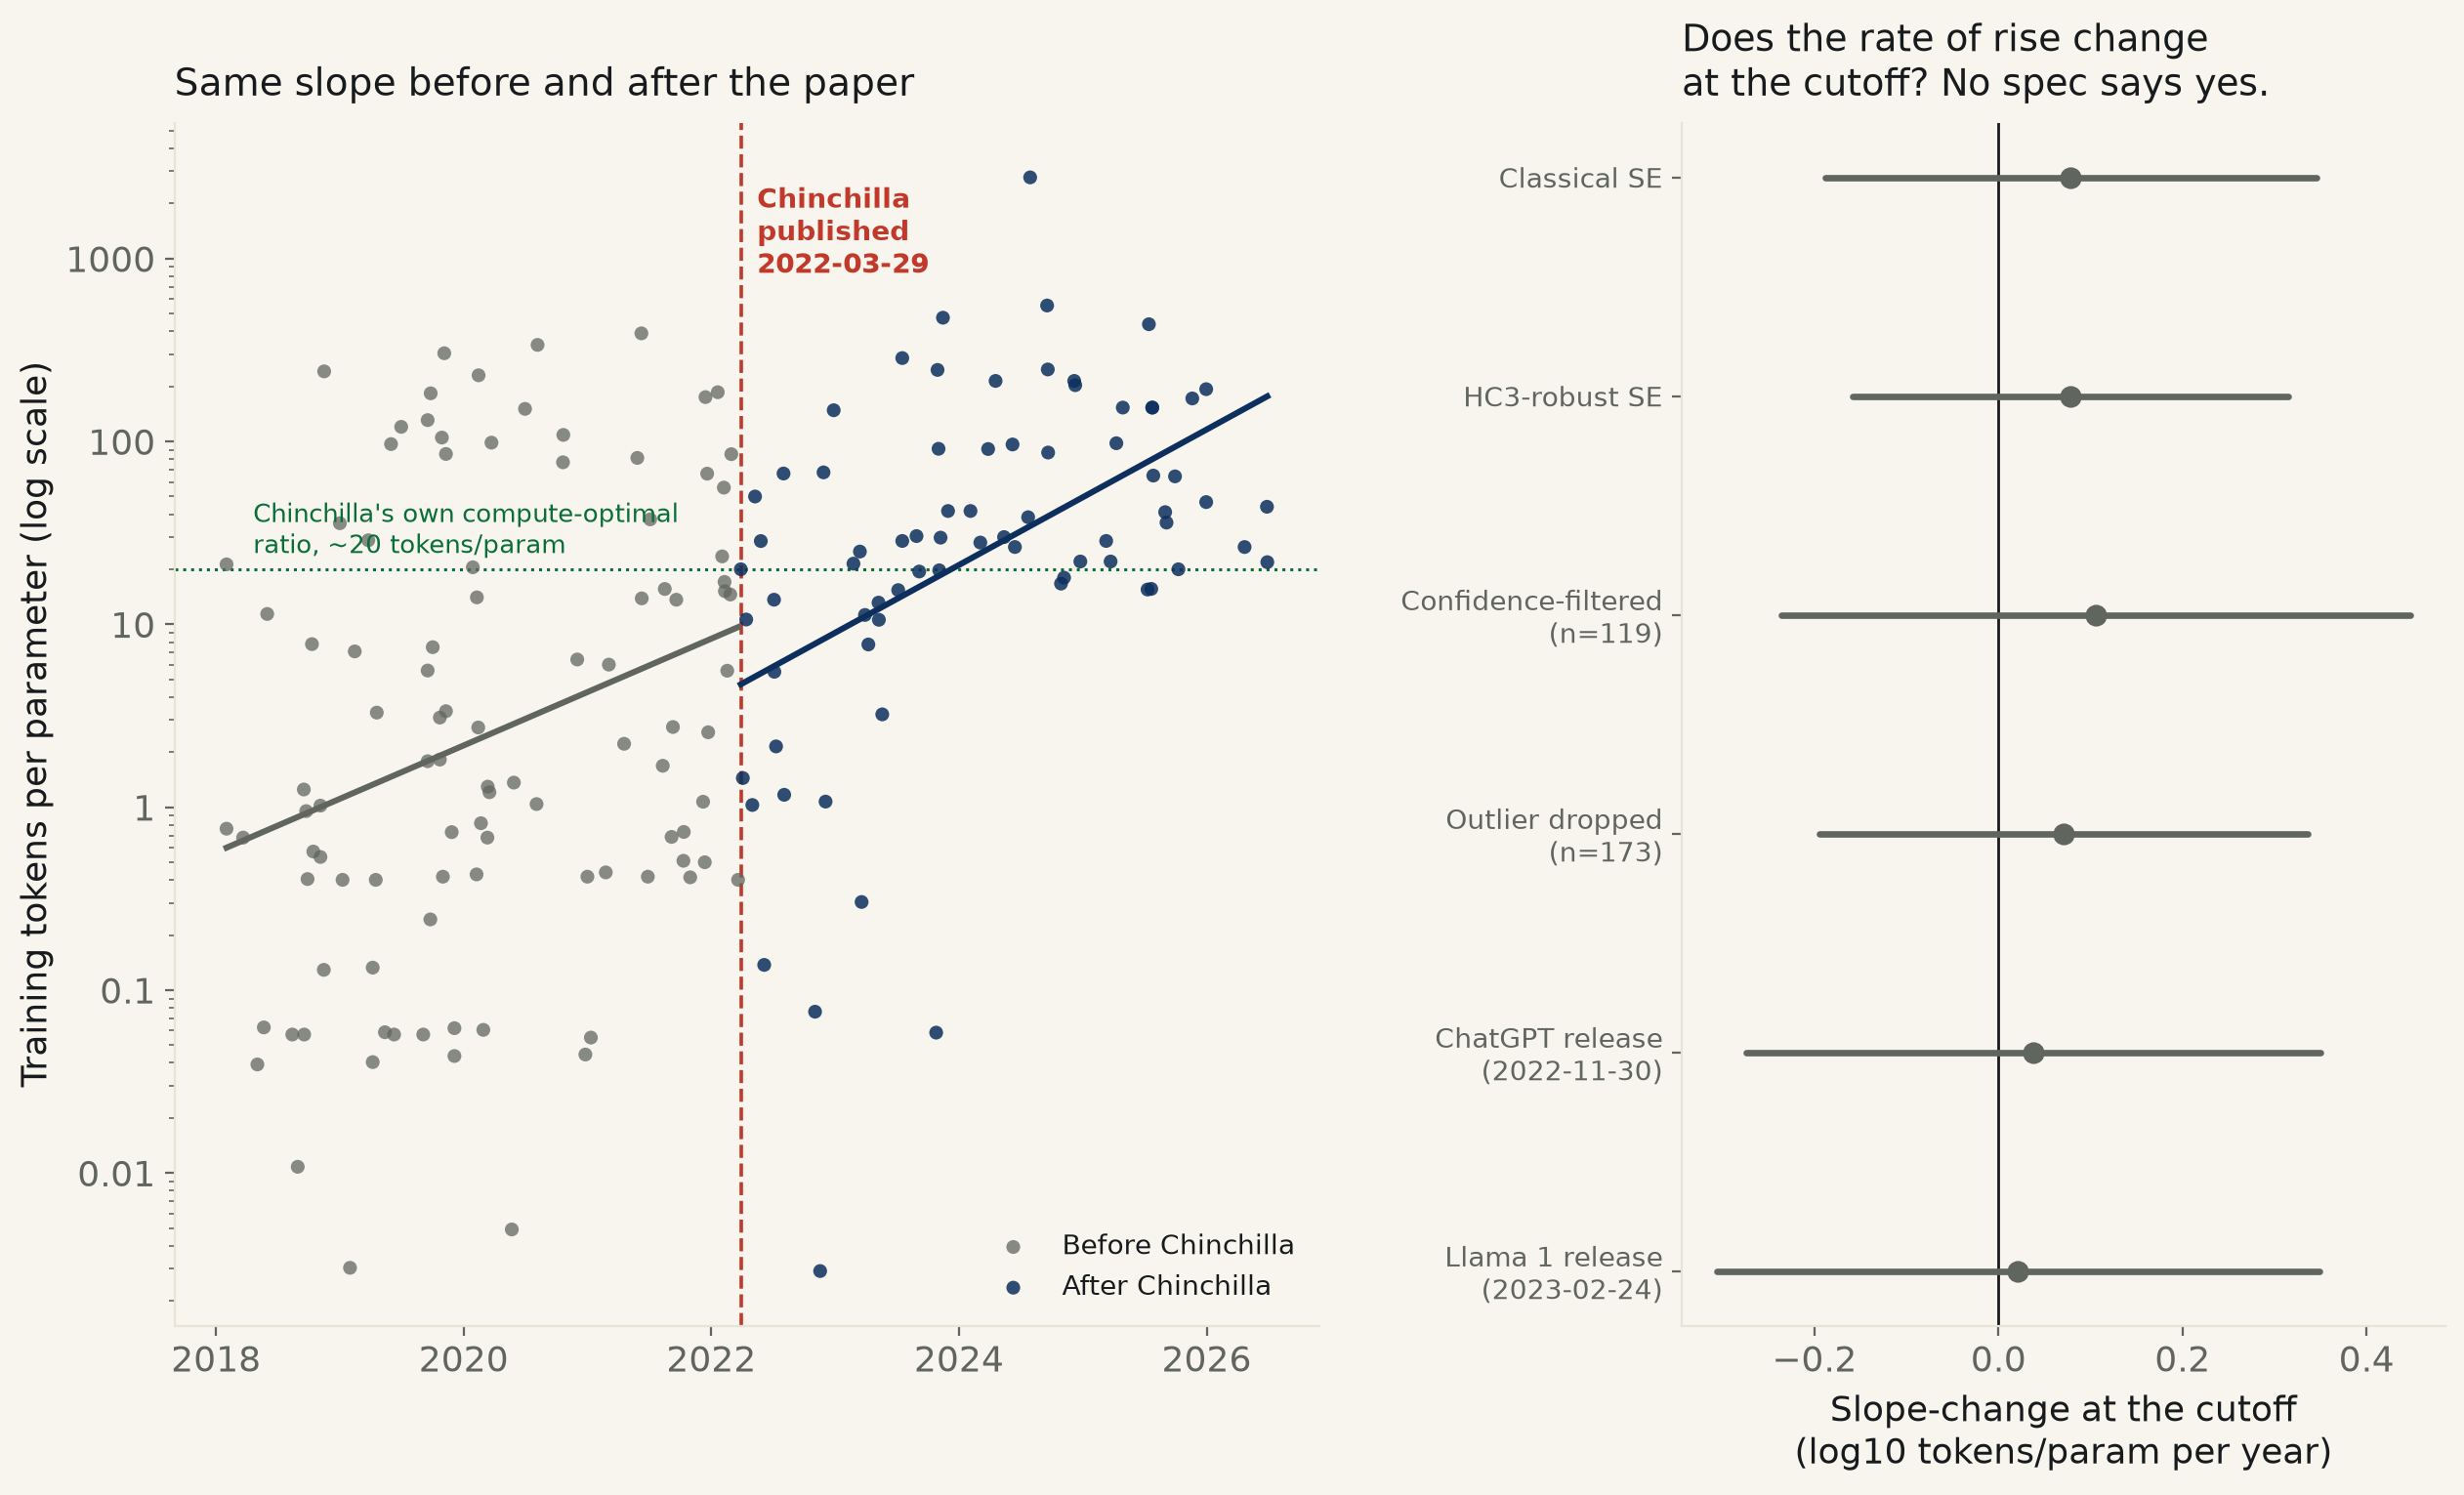
174 from-scratch, Language-domain models, 2018-2026, Epoch AI's own Notable AI Models dataset. Tokens-per-parameter ratio has risen +0.270 log₁₀ units/yr, 95% CI [+0.200, +0.340] — excludes zero. But the slope-change exactly at Chinchilla's own 2022-03-29 publication date is +0.079, CI [-0.188, +0.345] — contains zero, under all six specifications tried.
Backlog #96: “Chinchilla, checked — does more data beat more parameters?” DeepMind's 2022 paper (Hoffmann et al., “Training Compute-Optimal Large Language Models,” arXiv:2203.15556, submitted 2022-03-29) argued that the field's biggest models — GPT-3, Gopher, PaLM — were trained on too few tokens for their parameter count, and that a compute-optimal model should scale tokens and parameters together, landing near a 20-tokens-per-parameter ratio. The popular summary is “Chinchilla changed how everyone trains models.” This run tests whether the paper actually marks a break in the data, using Epoch AI's own public Notable AI Models dataset (keyless CSV): 174 from-scratch, Language-domain models, 2018-2026, with both a disclosed parameter count and a disclosed training-token count, dropping fine-tuned derivatives (whose reported training set is the fine-tuning data, not the pretraining corpus — a different, non-comparable ratio against the full inherited parameter count).
The ratio really has climbed, continuously, since 2018: log₁₀(tokens per parameter) rises +0.270 per year, 95% CI [+0.200, +0.340], p=1.5e-12, R²=0.253 — excludes zero. In plain terms, the typical model's tokens-per-parameter ratio has risen roughly 1.86× a year for eight straight years.
But the question this run exists to answer is narrower: did Chinchilla's own publication date mark a kink in that line? A model with a year term, a post-Chinchilla dummy, and their interaction tests exactly that — the interaction coefficient is the slope-change at the cutoff. It is +0.079, 95% CI [-0.188, +0.345], p=0.562 — contains zero. HC3-robust SE agrees: CI [-0.158, +0.315]. Fit separately, the pre-Chinchilla slope (+0.292, CI [+0.096, +0.488], n=100) and the post-Chinchilla slope (+0.370, CI [+0.204, +0.537], n=74) both individually exclude zero and sit on nearly the same line — the rise was already underway, and the paper did not visibly speed it up.
The null holds under every alternative specification tried. Restricting to Epoch's own “Confident”-confidence rows only (n=119): interaction +0.106, CI [-0.235, +0.448]. Dropping the single most extreme ratio in the sample (AFM-on-device, 2,779 tokens/param; n=173): +0.071, CI [-0.194, +0.336]. Substituting two other dates people commonly credit with “the shift” — ChatGPT's public release (+0.038, CI [-0.274, +0.350]) and Llama 1's release (+0.021, CI [-0.306, +0.349]) — returns the same null. No candidate date in this run finds a kink.
Named, for scale. GPT-3 175B (2020) trained at 1.4 tokens/param; Gopher 280B (2021), DeepMind's own prior flagship and the paper's lead example of undertraining, at 1.1. Chinchilla itself is in the dataset at exactly its own prescription, 70B params on 1.4T tokens, 20.0 tokens/param. By 2024, Llama 3-70B ran 214 tokens/param and Qwen2.5-32B ran 554 — both far past Chinchilla's own optimum, because at today's hardware and serving costs, a smaller model trained longer is cheaper to run forever after, even past the point that minimizes training compute alone. The share of models at or above Chinchilla's 20:1 ratio rose from 27% before the paper's date to 66% after it, and the median ratio rose from 1.8 to 28.6 — both real shifts in level across those two multi-year windows (bootstrap gap in mean log-ratio +0.966, CI [+0.628, +1.286], excludes zero) — but a level difference between two windows is not the same claim as a kink exactly at the boundary between them, and the break test above is the test built to tell those two claims apart.
Read plainly. “More data beats more parameters” is directionally true of the eight-year trend: the field really has moved toward training smaller models on much more data. But the data does not support crediting Chinchilla's own publication date with starting that movement, or even visibly accelerating it — the rate of rise before the paper and after it are statistically indistinguishable under six separate specifications. The more defensible read is that Chinchilla gave the field's own already-underway practice a theoretical name and a number, rather than causing a break in the practice itself.
Trend fits
| Specification | n | slope, log₁₀ tokens/param per yr | 95% CI | Fit | Verdict |
|---|---|---|---|---|---|
| Full sample, 2018-2026 | n=174 | +0.270 | [+0.200, +0.340] | R²=0.253 | excludes zero, p=1.5e-12 |
| Before Chinchilla only | n=100 | +0.292 | [+0.096, +0.488] | R²=0.082 | excludes zero, p=0.004 |
| After Chinchilla only | n=74 | +0.370 | [+0.204, +0.537] | R²=0.215 | excludes zero, p=3.2e-05 |
Break test: does the slope change at the candidate cutoff? (the coefficient on post·year — this is the test the run's headline rests on)
| Break-test specification (candidate date the slope might kink at) | n | slope-change coefficient | 95% CI | Verdict |
|---|---|---|---|---|
| Classical SE | n=174 | +0.079 | [-0.188, +0.345] | contains zero, p=0.562 |
| HC3-robust SE | n=174 | +0.079 | [-0.158, +0.315] | contains zero, p=0.516 |
| Confidence-filtered | n=119 | +0.106 | [-0.235, +0.448] | contains zero, p=0.539 |
| Outlier dropped (AFM-on-device) | n=173 | +0.071 | [-0.194, +0.336] | contains zero, p=0.599 |
| ChatGPT release (2022-11-30) | n=174 | +0.038 | [-0.274, +0.350] | contains zero, p=0.811 |
| Llama 1 release (2023-02-24) | n=174 | +0.021 | [-0.306, +0.349] | contains zero, p=0.899 |
Method. Epoch AI publishes a flat, keyless CSV export of its Notable AI Models database at epoch.ai/data/notable_ai_models.csv — every model the project judges notable by citation count, training compute, or historical significance, each row carrying parameter count, training dataset size, publication date, and a per-field confidence rating (Confident / Likely / Speculative) reflecting how directly each number is sourced. This run keeps rows with Domain == “Language”, both Parameters and Training dataset size (total) disclosed, publication date 2018-01-01 or later, and an empty Base model field — the last filter drops fine-tuned or instruction-tuned derivatives (InstructGPT, Flan-PaLM, CoEdiT, and similar), whose “training dataset” in the source records only the fine-tuning set, not the pretraining corpus, which would understate their effective ratio against the full parameter count they inherit from a base model. 174 rows survive every filter. “Before” and “after” Chinchilla are split at the paper's own arXiv submission timestamp, 2022-03-29.
Limits, stated plainly. Epoch's dataset selects for notability, not for a random or complete sample of all models ever trained — small, unremarkable models are underrepresented, especially in later years, which could bias the measured ratio in either direction depending on which models get written up. Parameter and token counts for proprietary models (GPT-4-class, for instance) are frequently estimates built from public statements or third-party analysis, not disclosed figures, and carry Epoch's own “Likely” or “Speculative” confidence tag rather than “Confident”; the confidence-filtered row in the break-test table shows the result is not solely an artifact of the less-certain rows, but does not make every individual number in the raw table certain. This run tests only whether the RATE of change in the ratio shifts at a handful of candidate dates — it cannot rule out a kink at some other date not tested, and it cannot speak to whether any individual lab explicitly cited the Chinchilla paper in choosing its own training recipe.
chinchilla_scaling_586.csv · fit output (JSON).
| Model | Organization | Published | Parameters | Training tokens | Tokens/param | Confidence |
|---|---|---|---|---|---|---|
| QRNN | Salesforce Research | 2018-02-01 | 135,000,000 | 103,000,000 | 0.76 | Likely |
| ELMo | University of Washington,Allen Institute for AI | 2018-02-01 | 94,000,000 | 2,000,000,000 | 21.28 | Speculative |
| 4 layer QRNN (h=2500) | Salesforce Research | 2018-03-22 | 151,000,000 | 103,000,000 | 0.68 | Likely |
| Dropout-LSTM+Noise(Bernoulli) (WT2) | Columbia University,New York University (NYU),Princeton University | 2018-05-03 | 51,000,000 | 2,000,000 | 0.04 | Likely |
| aLSTM(depth-2)+RecurrentPolicy (WT2) | University of Manchester,Alan Turing Institute | 2018-05-22 | 32,000,000 | 2,000,000 | 0.06 | Confident |
| GPT-1 | OpenAI | 2018-06-01 | 117,000,000 | 1,333,333,333 | 11.40 | Likely |
| AWD-LSTM-MoS+PDR + dynamic evaluation (WT2) | IBM | 2018-08-14 | 35,000,000 | 2,000,000 | 0.06 | Confident |
| (ensemble): AWD-LSTM-DOC (fin) × 5 (WT2) | NTT Communication Science Laboratories,Tohoku University | 2018-08-30 | 185,000,000 | 2,000,000 | 0.01 | Confident |
| Transformer + Simple Recurrent Unit | ASAPP,Cornell University,Google,Princeton University | 2018-09-17 | 90,000,000 | 112,500,000 | 1.25 | Confident |
| AWD-LSTM-MoS + dynamic evaluation (WT2, 2018) | Peking University,Microsoft Research Asia | 2018-09-18 | 35,000,000 | 2,000,000 | 0.06 | Confident |
| LSTM+NeuralCache | KU Leuven,ESAT - PSI,Apple | 2018-09-24 | 2,100,000 | 2,000,000 | 0.95 | Likely |
| Transformer (Adaptive Input Embeddings) WT103 | Facebook AI Research | 2018-09-28 | 247,000,000 | 100,000,000 | 0.40 | Confident |
| BERT-Large | 2018-10-11 | 340,000,000 | 2,649,900,000 | 7.79 | Confident | |
| TrellisNet | Carnegie Mellon University (CMU),Bosch Center for Artificial Intelligence,Intel Labs | 2018-10-15 | 180,000,000 | 103,000,000 | 0.57 | Confident |
| Mesh-TensorFlow Transformer 4.9B (language) | Google Brain | 2018-11-05 | 4,900,000,000 | 5,000,000,000 | 1.02 | Confident |
| Mesh-TensorFlow Transformer 2.9B (translation) | Google Brain | 2018-11-05 | 2,900,000,000 | 1,550,000,000 | 0.53 | Likely |
| Multi-cell LSTM | University of Hyderabad | 2018-11-15 | 7,200,000 | 929,000 | 0.13 | Likely |
| GPipe (Transformer) | 2018-11-16 | 6,000,000,000 | 1,450,000,000,000 | 241.67 | Likely | |
| Transformer ELMo | Allen Institute for AI,University of Washington | 2019-01-01 | 56,000,000 | 2,000,000,000 | 35.71 | Confident |
| Transformer-XL (257M) | Carnegie Mellon University (CMU),Google Brain | 2019-01-09 | 257,000,000 | 103,000,000 | 0.40 | Speculative |
| MT-DNN | Microsoft | 2019-01-31 | 330,000,000 | 1,000,000 | 0.00 | Confident |
| GPT-2 (1.5B) | OpenAI | 2019-02-14 | 1,500,000,000 | 10,666,666,667 | 7.11 | Speculative |
| SciBERT | Allen Institute for AI | 2019-03-26 | 110,000,000 | 3,170,000,000 | 28.82 | Confident |
| WeNet (Penn Treebank) | Amazon | 2019-04-08 | 23,000,000 | 929,000 | 0.04 | Likely |
| True-Regularization+Finetune+Dynamic-Eval | Mobvoi,Williams College | 2019-04-08 | 7,000,000 | 929,000 | 0.13 | Confident |
| Transformer-XL + RMS dynamic eval | University of Edinburgh | 2019-04-17 | 257,000,000 | 103,000,000 | 0.40 | Confident |
| BERT-Large-CAS (PTB+WT2+WT103) | Amazon | 2019-04-20 | 395,000,000 | 1,300,000,000 | 3.29 | Likely |
| AWD-LSTM-DRILL + dynamic evaluation† (WT2) | IDIAP | 2019-05-14 | 34,000,000 | 2,000,000 | 0.06 | Likely |
| XLNet | Carnegie Mellon University (CMU),Google Brain | 2019-06-01 | 340,000,000 | 32,890,000,000 | 96.74 | Confident |
| AWD-LSTM + MoS + Partial Shuffled | University of Texas at Austin | 2019-06-10 | 35,000,000 | 2,000,000 | 0.06 | Confident |
| RoBERTa Large | Facebook,University of Washington | 2019-07-01 | 355,000,000 | 42,666,666,666 | 120.19 | Confident |
| Mogrifier (d2, MoS2, MC) + dynamic eval | DeepMind,University of Oxford | 2019-09-04 | 35,000,000 | 2,000,000 | 0.06 | Confident |
| Megatron-LM (8.3B) | Nvidia | 2019-09-17 | 8,300,000,000 | 46,400,000,000 | 5.59 | Likely |
| Megatron-LM (1.2B) | Nvidia | 2019-09-17 | 1,200,000,000 | 157,000,000,000 | 130.83 | Confident |
| Megatron-BERT | Nvidia | 2019-09-17 | 3,900,000,000 | 6,960,000,000 | 1.78 | Confident |
| Adaptive Inputs + LayerDrop | Facebook AI Research,LORIA | 2019-09-25 | 423,000,000 | 103,000,000 | 0.24 | Confident |
| ALBERT | Toyota Technological Institute at Chicago,Google Research | 2019-09-26 | 18,000,000 | 3,300,000,000 | 183.33 | Confident |
| DistilBERT | Hugging Face | 2019-10-02 | 66,000,000 | 495,000,000 | 7.50 | Confident |
| T5-11B | 2019-10-23 | 11,000,000,000 | 34,000,000,000 | 3.09 | Confident | |
| T5-3B | 2019-10-23 | 2,800,000,000 | 5,100,000,000 | 1.82 | Confident | |
| BART-large | Facebook AI | 2019-10-29 | 406,291,456 | 42,666,666,666 | 105.01 | Likely |
| Base LM + kNN LM + Continuous Cache | Stanford University,Facebook AI Research | 2019-11-01 | 247,000,000 | 103,000,000 | 0.42 | Likely |
| XLM-RoBERTa | Facebook AI | 2019-11-05 | 550,000,000 | 167,000,000,000 | 303.64 | Confident |
| Sandwich Transformer | Allen Institute for AI,Facebook AI Research | 2019-11-10 | 209,000,000 | 700,000,000 | 3.35 | Speculative |
| CamemBERT | Facebook,INRIA,Sorbonne University | 2019-11-10 | 335,000,000 | 28,615,771,780 | 85.42 | Confident |
| Transformer-XL DeFINE (141M) | University of Washington,Allen Institute for AI | 2019-11-27 | 141,000,000 | 103,000,000 | 0.73 | Speculative |
| MMLSTM (WT-2) | Beijing University of Posts and Telecommunications,University of West London | 2019-12-05 | 32,300,000 | 2,000,000 | 0.06 | Likely |
| MMLSTM (PTB) | Beijing University of Posts and Telecommunications,University of West London | 2019-12-05 | 21,300,000 | 929,000 | 0.04 | Likely |
| Meena | Google Brain | 2020-01-28 | 2,600,000,000 | 53,333,333,333 | 20.51 | Confident |
| TaLK Convolution | Carleton University | 2020-02-08 | 240,000,000 | 103,000,000 | 0.43 | Likely |
| ALBERT-xxlarge | Toyota Technological Institute at Chicago,Google | 2020-02-09 | 235,000,000 | 3,300,000,000 | 14.04 | Speculative |
| Turing-NLG | Microsoft | 2020-02-13 | 17,000,000,000 | 46,400,000,000 | 2.73 | Likely |
| FFN SwiGLU | 2020-02-14 | 220,000,000 | 50,600,083,456 | 230.00 | Confident | |
| Feedback Transformer | LORIA,University of Lorraine,Facebook AI Research | 2020-02-21 | 126,000,000 | 103,000,000 | 0.82 | Speculative |
| TCAN (WT2) | Nanjing University,Ant Group | 2020-02-28 | 33,000,000 | 2,000,000 | 0.06 | Confident |
| TransformerXL + spectrum control | University of California Los Angeles (UCLA),JD.com | 2020-03-11 | 151,000,000 | 103,000,000 | 0.68 | Speculative |
| Routing Transformer (WT-103) | Google Research | 2020-03-12 | 79,500,000 | 103,000,000 | 1.30 | Confident |
| Tensor-Transformer(1core)+PN (WT103) | University of California (UC) Berkeley | 2020-03-17 | 85,300,000 | 103,000,000 | 1.21 | Confident |
| ELECTRA | Stanford University,Google,Google Brain | 2020-03-23 | 335,000,000 | 33,000,000,000 | 98.51 | Likely |
| Retrieval-Augmented Generator | Facebook,New York University (NYU),University College London (UCL) | 2020-05-22 | 626,000,000 | 3,074,560 | 0.00 | Confident |
| GPT-3 175B (davinci) | OpenAI | 2020-05-28 | 174,600,000,000 | 238,000,000,000 | 1.36 | Confident |
| GShard (dense) | 2020-06-30 | 2,300,000,000 | 346,666,666,667 | 150.72 | Confident | |
| DeLighT | University of Washington,Allen Institute for AI,Facebook AI Research | 2020-08-03 | 99,000,000 | 103,000,000 | 1.04 | Likely |
| ERNIE-GEN (large) | Baidu | 2020-08-06 | 340,000,000 | 114,666,666,667 | 337.25 | Speculative |
| mT5-XXL | Google,Google Research | 2020-10-20 | 13,000,000,000 | 1,000,000,000,000 | 76.92 | Confident |
| German ELECTRA Large | deepset,Bayerische Staatsbibliothek Muenchen | 2020-10-21 | 335,000,000 | 36,383,733,333 | 108.61 | Confident |
| CPM-Large | Tsinghua University,Beijing Academy of Artificial Intelligence / BAAI | 2020-12-01 | 2,600,000,000 | 16,700,000,000 | 6.42 | Confident |
| CT-MoS (WT2) | Google,National Tsing Hua University | 2020-12-25 | 45,000,000 | 2,000,000 | 0.04 | Confident |
| ERNIE-Doc (247M) | Baidu | 2020-12-31 | 247,000,000 | 103,000,000 | 0.42 | Confident |
| Switch | 2021-01-11 | 1,571,000,000,000 | 86,400,000,000 | 0.05 | Confident | |
| SRU++ Large | ASAPP | 2021-02-24 | 234,000,000 | 103,000,000 | 0.44 | Confident |
| Generative BST | Facebook AI Research | 2021-03-05 | 9,431,810,048 | 56,800,000,000 | 6.02 | Confident |
| PLUG | Alibaba | 2021-04-19 | 27,000,000,000 | 60,000,000,000 | 2.22 | Confident |
| ByT5-XXL | Google,Google Research | 2021-05-28 | 12,900,000,000 | 1,048,576,000,000 | 81.28 | Likely |
| EMDR | Mila - Quebec AI (originally Montreal Institute for Learning Algorithms),McGill University,DeepMind | 2021-06-09 | 440,000,000 | 171,600,000,000 | 390.00 | Confident |
| DeBERTa | Microsoft | 2021-06-10 | 1,500,000,000 | 20,800,000,000 | 13.87 | Confident |
| Adaptive Input Transformer + RD | Microsoft Research Asia,Soochow University | 2021-06-28 | 247,000,000 | 103,000,000 | 0.42 | Likely |
| ERNIE 3.0 | Baidu | 2021-07-05 | 10,000,000,000 | 375,000,000,000 | 37.50 | Confident |
| Jurassic-1-Jumbo | AI21 Labs | 2021-08-11 | 178,000,000,000 | 300,000,000,000 | 1.69 | Confident |
| XLMR-XXL | Facebook AI Research | 2021-08-17 | 10,700,000,000 | 167,000,000,000 | 15.61 | Confident |
| PermuteFormer | Peking University | 2021-09-06 | 149,697,024 | 103,000,000 | 0.69 | Speculative |
| HyperCLOVA 204B | NAVER | 2021-09-10 | 204,000,000,000 | 560,000,000,000 | 2.75 | Speculative |
| PLATO-XL | Baidu | 2021-09-20 | 11,000,000,000 | 150,000,000,000 | 13.64 | Confident |
| Megatron-Turing NLG 530B | Microsoft,Nvidia | 2021-10-11 | 530,000,000,000 | 270,000,000,000 | 0.51 | Confident |
| Yuan 1.0 | Inspur | 2021-10-12 | 245,730,000,000 | 180,000,000,000 | 0.73 | Confident |
| S4 | Stanford University | 2021-10-31 | 249,000,000 | 103,000,000 | 0.41 | Likely |
| Gopher (280B) | DeepMind | 2021-12-08 | 280,000,000,000 | 300,000,000,000 | 1.07 | Confident |
| GLaM | 2021-12-13 | 1,200,000,000,000 | 600,000,000,000 | 0.50 | Confident | |
| LongT5 | Google Research | 2021-12-15 | 3,000,000,000 | 524,288,000,000 | 174.76 | Confident |
| XGLM-7.5B | Meta AI,Facebook AI Research | 2021-12-20 | 7,500,000,000 | 500,000,000,000 | 66.67 | Confident |
| ERNIE 3.0 Titan | Baidu,Peng Cheng Laboratory | 2021-12-23 | 260,000,000,000 | 668,000,000,000 | 2.57 | Confident |
| data2vec (language) | Meta AI | 2022-01-20 | 705,134,592 | 131,072,000,000 | 185.88 | Likely |
| AlphaCode | DeepMind | 2022-02-02 | 41,100,000,000 | 967,000,000,000 | 23.53 | Confident |
| RETRO-7B | DeepMind | 2022-02-07 | 7,500,000,000 | 419,430,400,000 | 55.92 | Confident |
| GPT-NeoX-20B | EleutherAI | 2022-02-09 | 20,000,000,000 | 341,173,367,965 | 17.06 | Confident |
| LaMDA | 2022-02-10 | 137,000,000,000 | 2,080,000,000,000 | 15.18 | Confident | |
| ST-MoE | Google,Google Brain,Google Research | 2022-02-17 | 269,000,000,000 | 1,500,000,000,000 | 5.58 | Likely |
| PolyCoder | Carnegie Mellon University (CMU) | 2022-02-26 | 2,700,000,000 | 39,300,000,000 | 14.56 | Likely |
| DeepNet | Microsoft Research | 2022-03-01 | 3,200,000,000 | 272,629,760,000 | 85.20 | Confident |
| Segatron-XL large, M=384 + HCP | Microsoft Research,University of Waterloo | 2022-03-21 | 257,000,000 | 103,000,000 | 0.40 | Confident |
| Chinchilla | DeepMind | 2022-03-29 | 70,000,000,000 | 1,400,000,000,000 | 20.00 | Confident |
| PaLM (540B) | Google Research | 2022-04-04 | 540,350,000,000 | 780,000,000,000 | 1.44 | Confident |
| Sparse all-MLP | Meta AI | 2022-04-14 | 9,410,000,000 | 100,000,000,000 | 10.63 | Confident |
| OPT-175B | Meta AI | 2022-05-02 | 175,000,000,000 | 180,000,000,000 | 1.03 | Confident |
| UL2 | Google Research,Google Brain | 2022-05-10 | 20,000,000,000 | 1,000,000,000,000 | 50.00 | Confident |
| GPT-2 Medium (FlashAttention) | Stanford University,University at Buffalo | 2022-05-27 | 355,000,000 | 10,130,000,000 | 28.54 | Confident |
| DITTO | Tsinghua University,Apple,Westlake University,Chinese University of Hong Kong (CUHK) | 2022-06-06 | 750,000,000 | 103,000,000 | 0.14 | Confident |
| CodeT5-large | Salesforce | 2022-07-05 | 770,000,000 | 10,500,000,000 | 13.64 | Likely |
| NLLB | Meta AI | 2022-07-06 | 54,500,000,000 | 300,000,000,000 | 5.50 | Confident |
| BLOOM-176B | Hugging Face,BigScience | 2022-07-11 | 176,247,271,424 | 379,000,000,000 | 2.15 | Confident |
| AlexaTM 20B | Amazon | 2022-08-02 | 19,750,000,000 | 1,319,000,000,000 | 66.78 | Confident |
| GLM-130B | Tsinghua University | 2022-08-04 | 130,000,000,000 | 152,000,000,000 | 1.17 | Confident |
| Mogrifier RLSTM (WT2) | DeepMind | 2022-11-03 | 35,000,000 | 2,666,667 | 0.08 | Confident |
| Fusion in Encoder | Samsung | 2022-11-18 | 330,000,000 | 960,000 | 0.00 | Likely |
| ALM 1.0 | Beijing Academy of Artificial Intelligence / BAAI | 2022-11-28 | 335,000,000 | 22,696,572,400 | 67.75 | Speculative |
| Vega v2 | Wuhan University,JD Explore Academy,Shanghai AI Lab,Nanyang Technological University,Washington University in St Louis,Chongqing University of Posts and Telecommunications,University of Sydney | 2022-12-04 | 6,000,000,000 | 6,439,999,999 | 1.07 | Confident |
| Hybrid H3-2.7B | Stanford University,University at Buffalo | 2022-12-28 | 2,700,000,000 | 400,000,000,000 | 148.15 | Likely |
| LLaMA-65B | Meta AI | 2023-02-24 | 65,200,000,000 | 1,400,000,000,000 | 21.47 | Confident |
| Falcon-40B | Technology Innovation Institute | 2023-03-15 | 40,000,000,000 | 1,000,000,000,000 | 25.00 | Confident |
| PanGu-Σ | Huawei Noah's Ark Lab | 2023-03-20 | 1,085,000,000,000 | 329,000,000,000 | 0.30 | Confident |
| BloombergGPT | Bloomberg,Johns Hopkins University | 2023-03-30 | 50,558,868,480 | 569,000,000,000 | 11.25 | Confident |
| Incoder-6.7B | Facebook AI Research,University of Washington,University of California (UC) Berkeley,Carnegie Mellon University (CMU),Toyota Technological Institute at Chicago | 2023-04-09 | 6,700,000,000 | 52,000,000,000 | 7.76 | Confident |
| StarCoder | Hugging Face,ServiceNow,Northeastern University,Mila - Quebec AI (originally Montreal Institute for Learning Algorithms),Carnegie Mellon University (CMU),Johns Hopkins University,Leipzig University,ScaDS.AI,Queen Mary University of London,Roblox,Sea AI Lab,Technion - Israel Institute of Technology,Monash University,CSIRO,Data61,McGill University,Saama,University of British Columbia (UBC),Massachusetts Institute of Technology (MIT),Technical University of Munich,IBM,University of Vermont,UnfoldML,SAP,University of Notre Dame,Columbia University,New York University (NYU),University of Allahabad,Discover Dollar,Toloka,Telefonica,Stanford University,Weizmann Institute of Science,Alan Turing Institute,Wellesley College,EleutherAI,Forschungszentrum Julich | 2023-05-09 | 15,500,000,000 | 203,750,000,000 | 13.15 | Confident |
| PaLM 2 | 2023-05-10 | 340,000,000,000 | 3,600,000,000,000 | 10.59 | Likely | |
| CodeT5+ | Salesforce | 2023-05-20 | 16,000,000,000 | 51,500,000,000 | 3.22 | Confident |
| InternLM | Shanghai AI Lab,SenseTime | 2023-07-06 | 104,000,000,000 | 1,600,000,000,000 | 15.38 | Confident |
| Llama 2-70B | Meta AI | 2023-07-18 | 70,000,000,000 | 2,000,000,000,000 | 28.57 | Confident |
| Llama 2-7B | Meta AI | 2023-07-18 | 7,000,000,000 | 2,000,000,000,000 | 285.71 | Confident |
| Jais | Cerebras Systems,Mohamed bin Zayed University of Artificial Intelligence (MBZUAI),Inception G42 | 2023-08-29 | 13,000,000,000 | 395,000,000,000 | 30.38 | Confident |
| Falcon-180B | Technology Innovation Institute | 2023-09-06 | 180,000,000,000 | 3,500,000,000,000 | 19.44 | Confident |
| CODEFUSION (Python) | Microsoft,Microsoft Research | 2023-10-26 | 75,000,000 | 4,390,400 | 0.06 | Confident |
| Skywork-13B | Kunlun Inc. | 2023-10-30 | 13,000,000,000 | 3,200,000,000,000 | 246.15 | Confident |
| Yi-34B | 01.AI | 2023-11-02 | 34,000,000,000 | 3,100,000,000,000 | 91.18 | Confident |
| Grok-1 | xAI | 2023-11-04 | 314,000,000,000 | 6,200,000,000,000 | 19.75 | Likely |
| RoFormer | Zhuiyi Technology | 2023-11-08 | 110,000,000 | 3,276,800,000 | 29.79 | Confident |
| Nemotron-3-8B | Nvidia | 2023-11-15 | 8,000,000,000 | 3,800,000,000,000 | 475.00 | Confident |
| Qwen-72B | Alibaba | 2023-11-30 | 72,000,000,000 | 3,000,000,000,000 | 41.67 | Confident |
| Qwen1.5-72B | Alibaba | 2024-02-04 | 72,000,000,000 | 3,000,000,000,000 | 41.67 | Confident |
| Aramco Metabrain AI | Saudi Aramco | 2024-03-04 | 250,000,000,000 | 7,000,000,000,000 | 28.00 | Likely |
| DBRX | Databricks | 2024-03-27 | 132,000,000,000 | 12,000,000,000,000 | 90.91 | Confident |
| Llama 3-70B | Meta AI | 2024-04-18 | 70,000,000,000 | 15,000,000,000,000 | 214.29 | Confident |
| Yi-Large | 01.AI | 2024-05-13 | 100,000,000,000 | 3,000,000,000,000 | 30.00 | Speculative |
| Qwen2-72B | Alibaba | 2024-06-07 | 72,710,000,000 | 7,000,000,000,000 | 96.27 | Confident |
| Nemotron-4 340B | Nvidia | 2024-06-14 | 340,000,000,000 | 9,000,000,000,000 | 26.47 | Confident |
| Llama 3.1-405B | Meta AI | 2024-07-23 | 405,000,000,000 | 15,600,000,000,000 | 38.52 | Confident |
| AFM-on-device | Apple | 2024-07-29 | 2,730,000,000 | 7,588,000,000,000 | 2779.49 | Confident |
| Qwen2.5-32B | Alibaba | 2024-09-17 | 32,500,000,000 | 18,000,000,000,000 | 553.85 | Confident |
| Qwen2.5-72B | Alibaba | 2024-09-19 | 72,700,000,000 | 18,000,000,000,000 | 247.59 | Confident |
| Telechat2-115B | China Telecom | 2024-09-20 | 115,000,000,000 | 10,000,000,000,000 | 86.96 | Confident |
| Doubao-pro | ByteDance | 2024-10-28 | 500,000,000,000 | 8,350,000,000,000 | 16.70 | Likely |
| Hunyuan-Large | Tencent | 2024-11-06 | 389,000,000,000 | 7,000,000,000,000 | 17.99 | Confident |
| Llama 3.3 70B | Meta AI | 2024-12-06 | 70,000,000,000 | 15,000,000,000,000 | 214.29 | Confident |
| EXAONE 3.5 32B | LG AI Research | 2024-12-09 | 32,000,000,000 | 6,500,000,000,000 | 203.12 | Confident |
| DeepSeek-V3 | DeepSeek | 2024-12-24 | 671,000,000,000 | 14,800,000,000,000 | 22.06 | Confident |
| Hunyuan-TurboS | Tencent | 2025-03-11 | 560,000,000,000 | 16,000,000,000,000 | 28.57 | Confident |
| DeepSeek-V3 (Mar 2025) | DeepSeek | 2025-03-24 | 671,000,000,000 | 14,800,000,000,000 | 22.06 | Confident |
| Pangu Ultra | Huawei | 2025-04-10 | 135,000,000,000 | 13,200,000,000,000 | 97.78 | Confident |
| Qwen3-235B-A22B | Alibaba | 2025-04-29 | 235,000,000,000 | 36,000,000,000,000 | 153.19 | Likely |
| Kimi K2 | Moonshot | 2025-07-11 | 1,000,000,000,000 | 15,500,000,000,000 | 15.50 | Confident |
| EXAONE 4.0 (32B) | LG AI Research | 2025-07-15 | 32,000,000,000 | 14,000,000,000,000 | 437.50 | Confident |
| Qwen3-Coder-480B-A35B | Alibaba | 2025-07-22 | 480,000,000,000 | 7,500,000,000,000 | 15.62 | Confident |
| Qwen3-235B-A22B-Thinking (Jul 2025) | Alibaba | 2025-07-25 | 235,000,000,000 | 36,000,000,000,000 | 153.19 | Likely |
| Qwen3-235B-A22B (Jul 2025) | Alibaba | 2025-07-25 | 235,000,000,000 | 36,000,000,000,000 | 153.19 | Likely |
| GLM-4.5 | Z.ai (Zhipu AI),Tsinghua University | 2025-07-28 | 355,000,000,000 | 23,100,000,000,000 | 65.07 | Confident |
| LongCat-Flash | Meituan Inc | 2025-09-01 | 560,000,000,000 | 23,000,000,000,000 | 41.07 | Likely |
| Qwen3-Max | Alibaba | 2025-09-05 | 1,000,000,000,000 | 36,000,000,000,000 | 36.00 | Speculative |
| GLM-4.6 | Z.ai (Zhipu AI),Tsinghua University | 2025-09-30 | 357,000,000,000 | 23,000,000,000,000 | 64.43 | Likely |
| Ling-1T | Ant Group | 2025-10-10 | 1,000,000,000,000 | 20,000,000,000,000 | 20.00 | Confident |
| Olmo 3 | Allen Institute for AI | 2025-11-20 | 32,000,000,000 | 5,500,000,000,000 | 171.88 | Confident |
| Solar Open 100B | Upstage | 2025-12-31 | 102,000,000,000 | 19,700,000,000,000 | 193.14 | Confident |
| K-EXAONE | LG AI Research | 2025-12-31 | 236,000,000,000 | 11,000,000,000,000 | 46.61 | Confident |
| MiMo-V2.5-Pro | Xiaomi Corp | 2026-04-23 | 1,020,000,000,000 | 27,000,000,000,000 | 26.47 | Likely |
| Solar Open2 250B | Upstage | 2026-06-28 | 250,300,000,000 | 11,000,000,000,000 | 43.95 | Likely |
| LongCat-2.0 | Meituan Inc | 2026-06-29 | 1,600,000,000,000 | 35,000,000,000,000 | 21.88 | Likely |